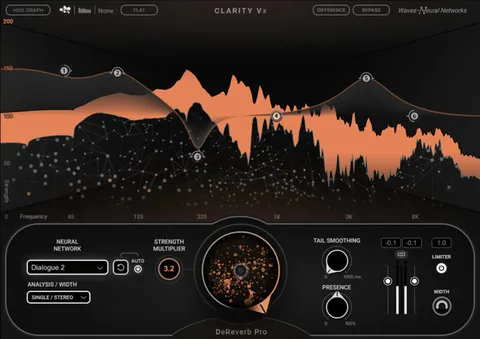
Deep learning dialogue reverb reduction
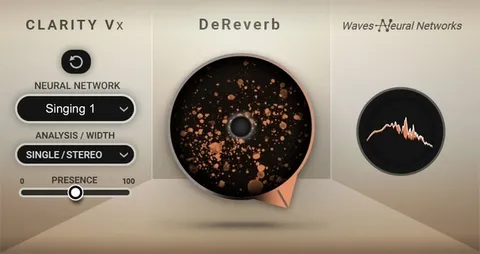
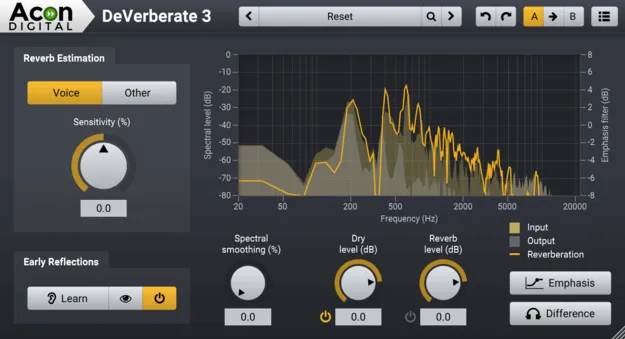
The automatic mode uses a neural network trained on thousands of high-quality voice recordings across a wide variety of acoustic spaces. According to Acon Digital, the network learns to separate dialogue from reverb without manual tuning.
For music and other signal types, a manual mode gives you control over the original reverberation's level and decay times. You can adjust the direct sound and the reverberation levels separately, then recombine them.